Local inference
Qwen3.6-35B-A3B · MTP · NVFP4
32 GB RAM laptop: every weight resident in memory
MSI Prestige 16 AI+ C3MTG · Core Ultra X7 358H · 32 GB
One captured run per system
With 32 GB every weight fits in memory on both systems. This pair compares captured generation rates for the same weights and the same kind of request, a merge sort in C.
- Laptop
- MSI Prestige 16 AI+ C3MTG
- CPU
- Intel Core Ultra X7 358H
- GPU
- Intel Arc B390 · Xe3 (integrated)
- Memory
- 32 GB, shared by CPU, GPU and NPU
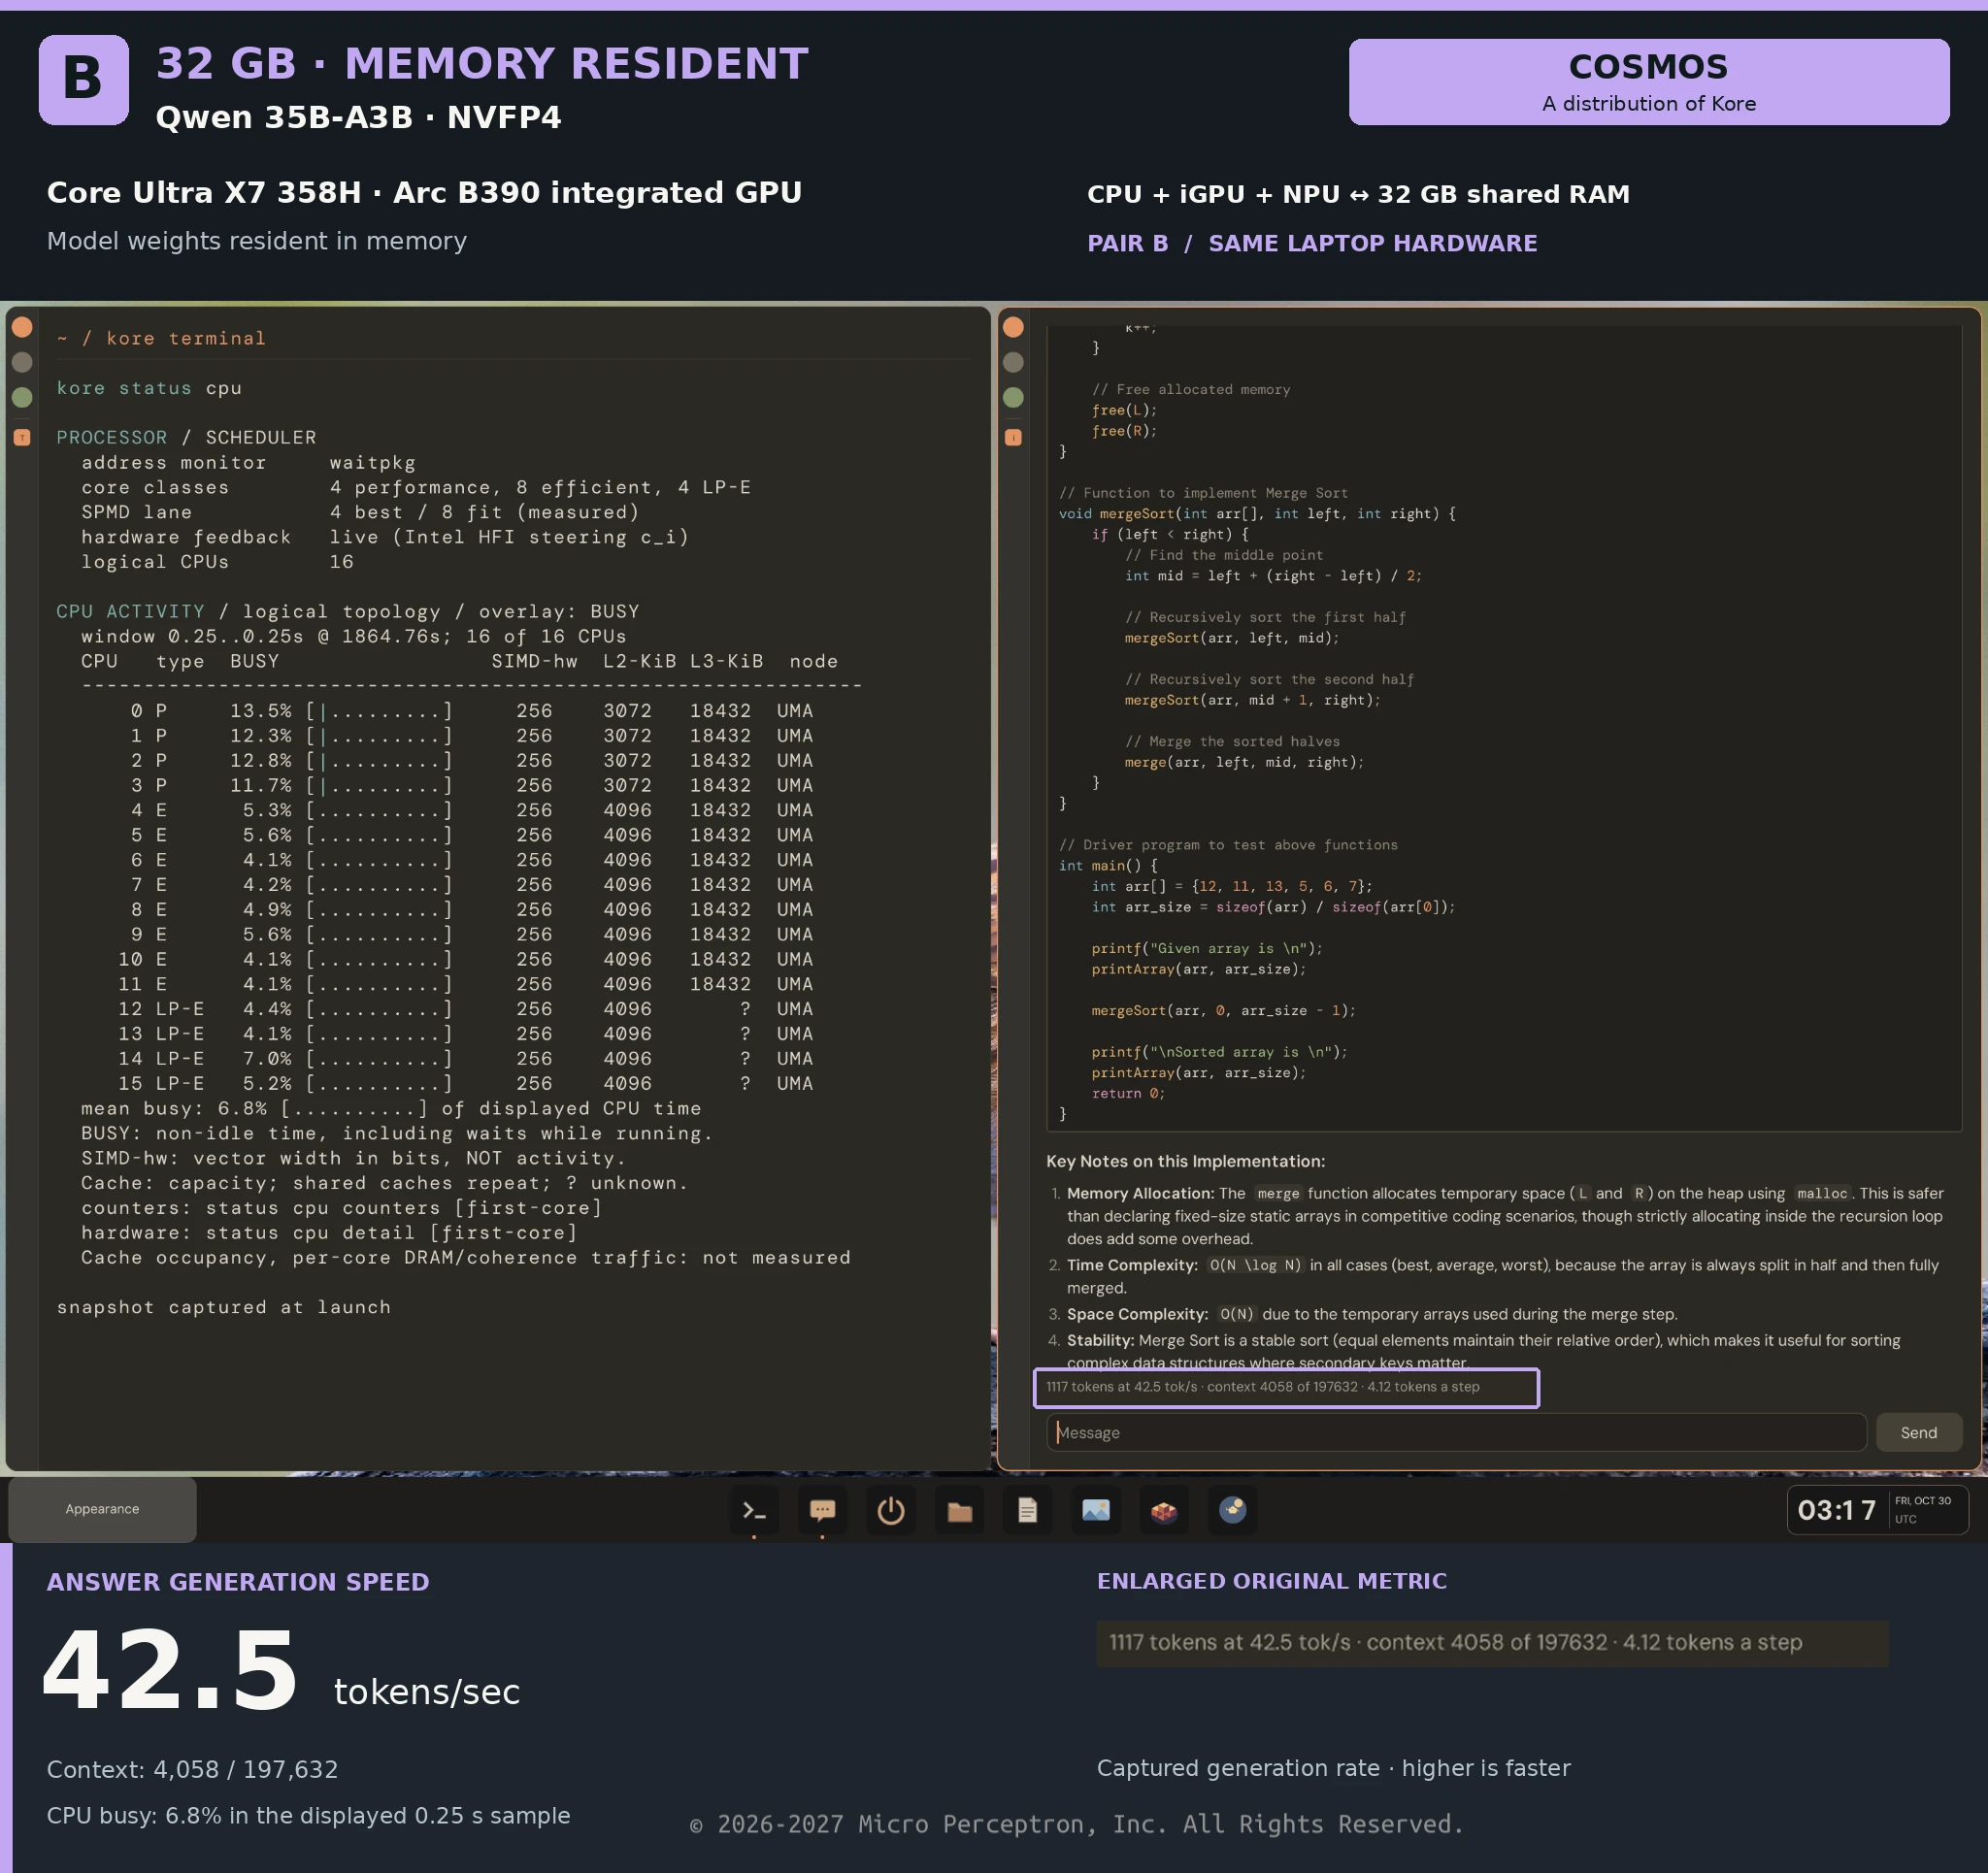
42.5tok/s
Decode speed on this laptop · 2.8× the speed of Ubuntu + llama.cpp on the same machine
- Cosmos
- 42.5tok/s
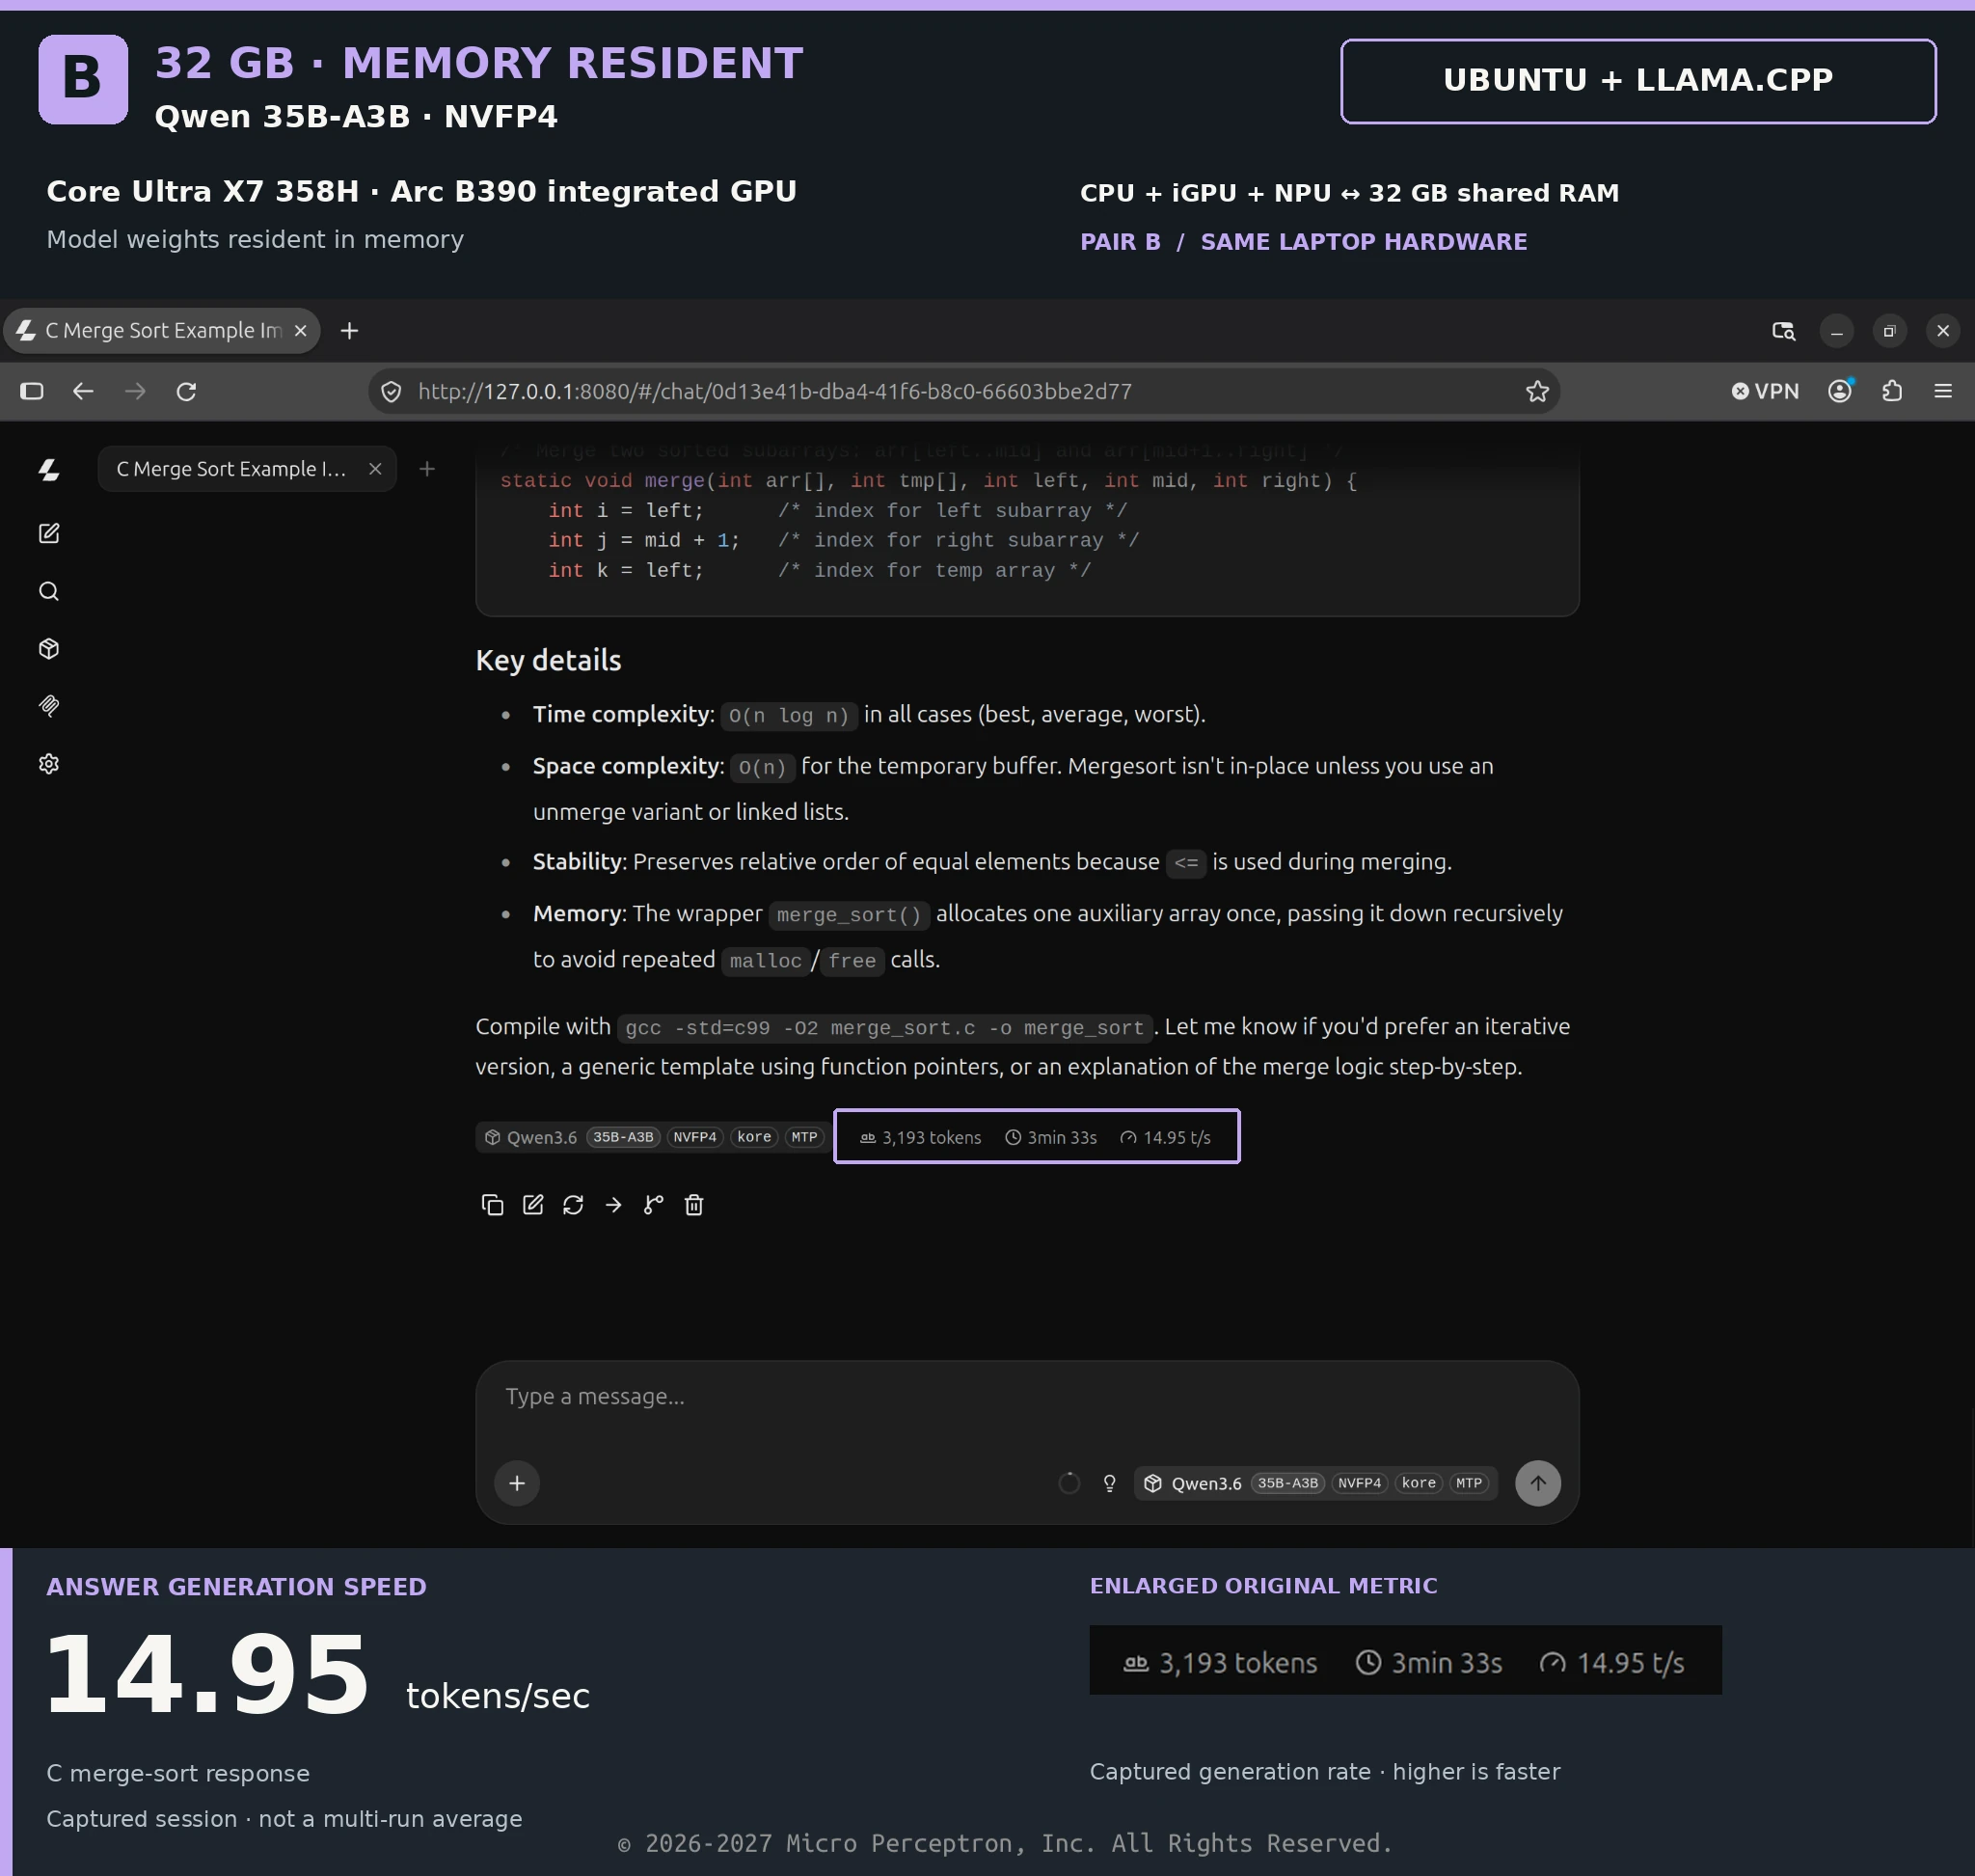
- Ubuntu + llama.cpp
- 14.95tok/s
Readouts, as shown on screen
Cosmos
1117 tokens at 42.5 tok/s · context 4058 of 197632 · 4.12 tokens a step
Context 4,058 / 197,632 · 4.12 tokens per decode step
Ubuntu + llama.cpp
3,193 tokens · 3min 33s · 14.95 t/s
3,193 tokens in 3 min 33 s
What each system ran
- Weights
- BothQwen3.6-35B-A3B · MTP · NVFP4
- System
- CosmosCosmos on Kore
- Ubuntu + llama.cppUbuntu 26.04.1 LTS · Linux 7.0.0-38 · latest Intel Xe drivers
- Runtime
- CosmosKore's inference engine · built-in chat
- Ubuntu + llama.cppllama.cpp 0.8 · native NVFP4 · expert-cache support · web UI
Evidence
 (open full size)
 (open full size)
How it was measured
- Same machine
- Every comparison ran on one laptop, with the same silicon, drive and model weights on each side. On metal, Cosmos and Ubuntu were booted in turn; a result that ran Cosmos as a guest says how the guest was set up.
- Current baseline
- Ubuntu 26.04.1 LTS on Linux 7.0.0-38 with the latest Intel Xe drivers, on both machines; llama.cpp 0.8, with native NVFP4 and expert-cache support; fio 3.41 with io_uring, direct I/O and registered buffers, as the storage result's commands show. Current releases, not old builds, with one exception: the 27B result's llama.cpp run used an earlier build whose version wasn't recorded, and its settings say so.
- Captured runs
- Each figure is one captured run, read off its screenshot — not an average of repeated runs.
- Native harnesses
- Each system is measured with its own tools: Cosmos's chat and pack bench; llama.cpp's web UI and fio on Ubuntu. Transfer sizes and scheduling are reported, not equalized.
- Units
- Storage in decimal GB/s (10⁹ bytes per second). Tokens per second as each runtime reports its own generation speed.
- Setup excluded
- Buffer allocation and registration happen before timing on both systems; Cosmos prints its setup time on a separate line.
More results
- Local inference32 GB RAM laptop: Qwen3.8-27B, every weight resident24.0 tok/s · 32 GB
- Local inference16 GB RAM laptop: a model larger than its memory, streamed from SSD13.2 tok/s · 16 GB
- As a guest32 GB RAM laptop: Cosmos as a guest of Ubuntu, on one virtual function of the GPU37.9 tok/s · 32 GB
- StorageNVMe raw read6.02 GB/s · 16 GB