Local inference
Qwen3.8-27B · QUASAR · MTP · NVFP4
32 GB RAM laptop: Qwen3.8-27B, every weight resident
MSI Prestige 16 AI+ C3MTG · Core Ultra X7 358H · 32 GB
One captured run per system
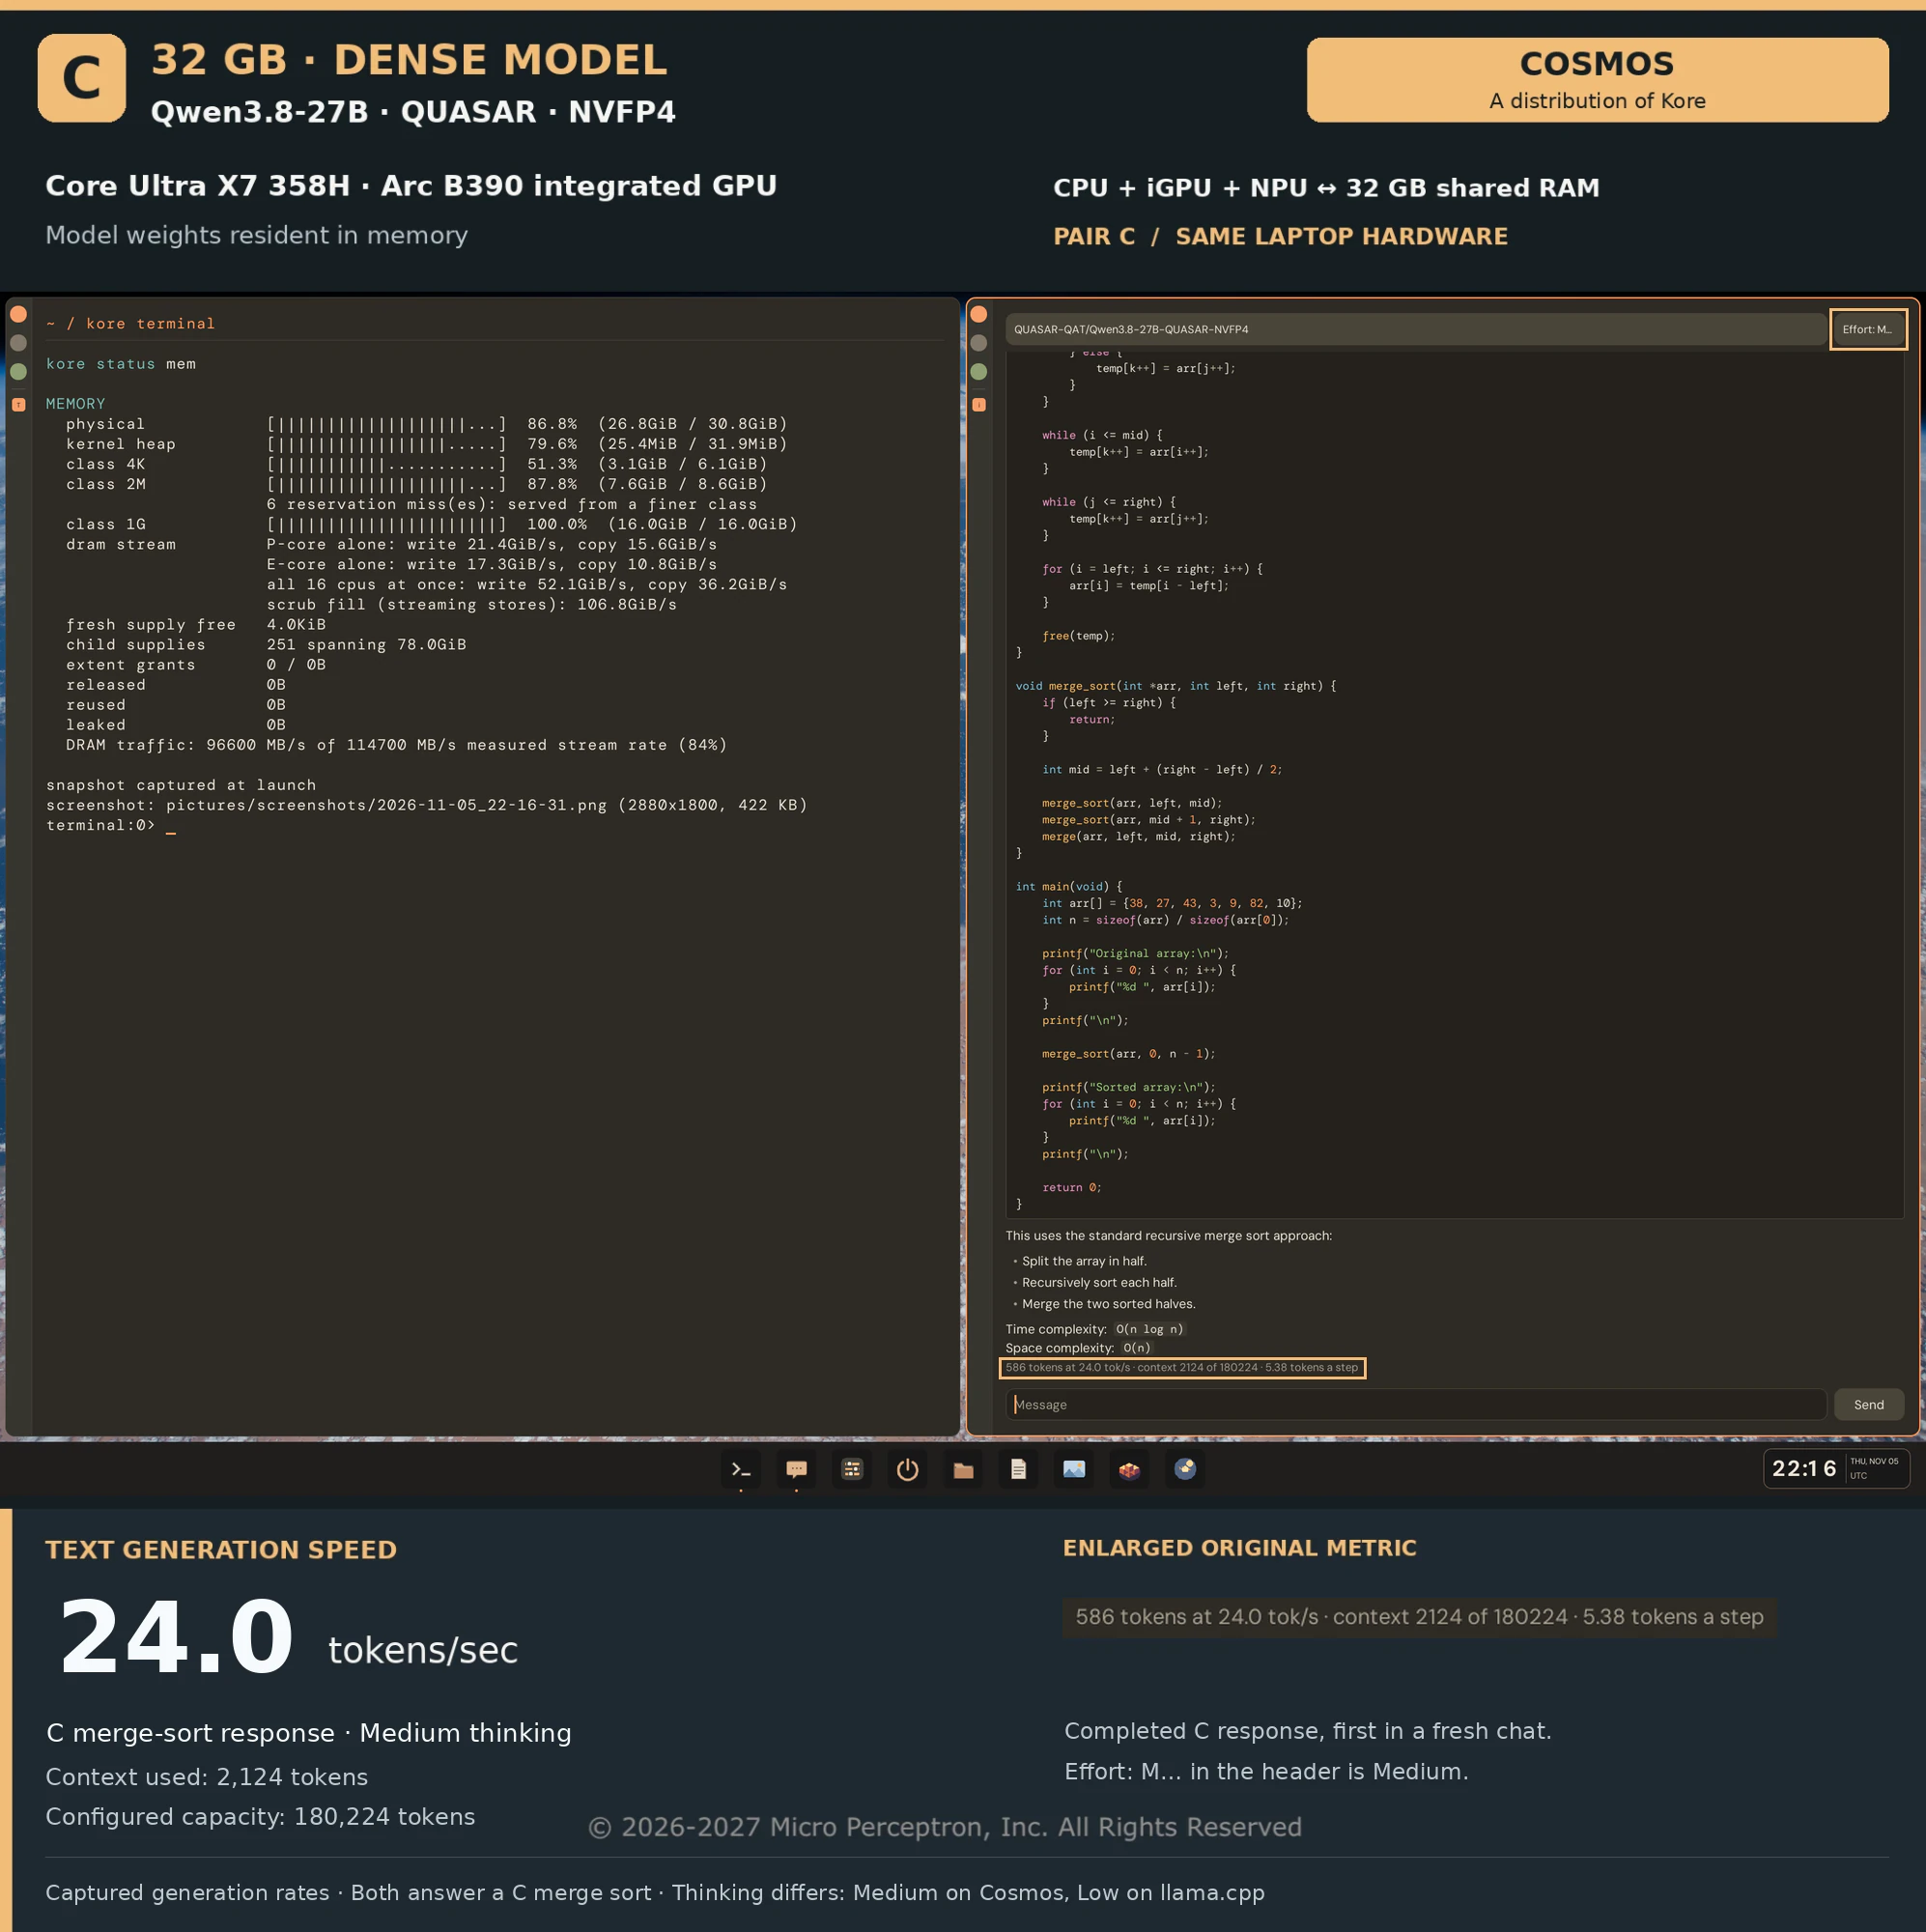
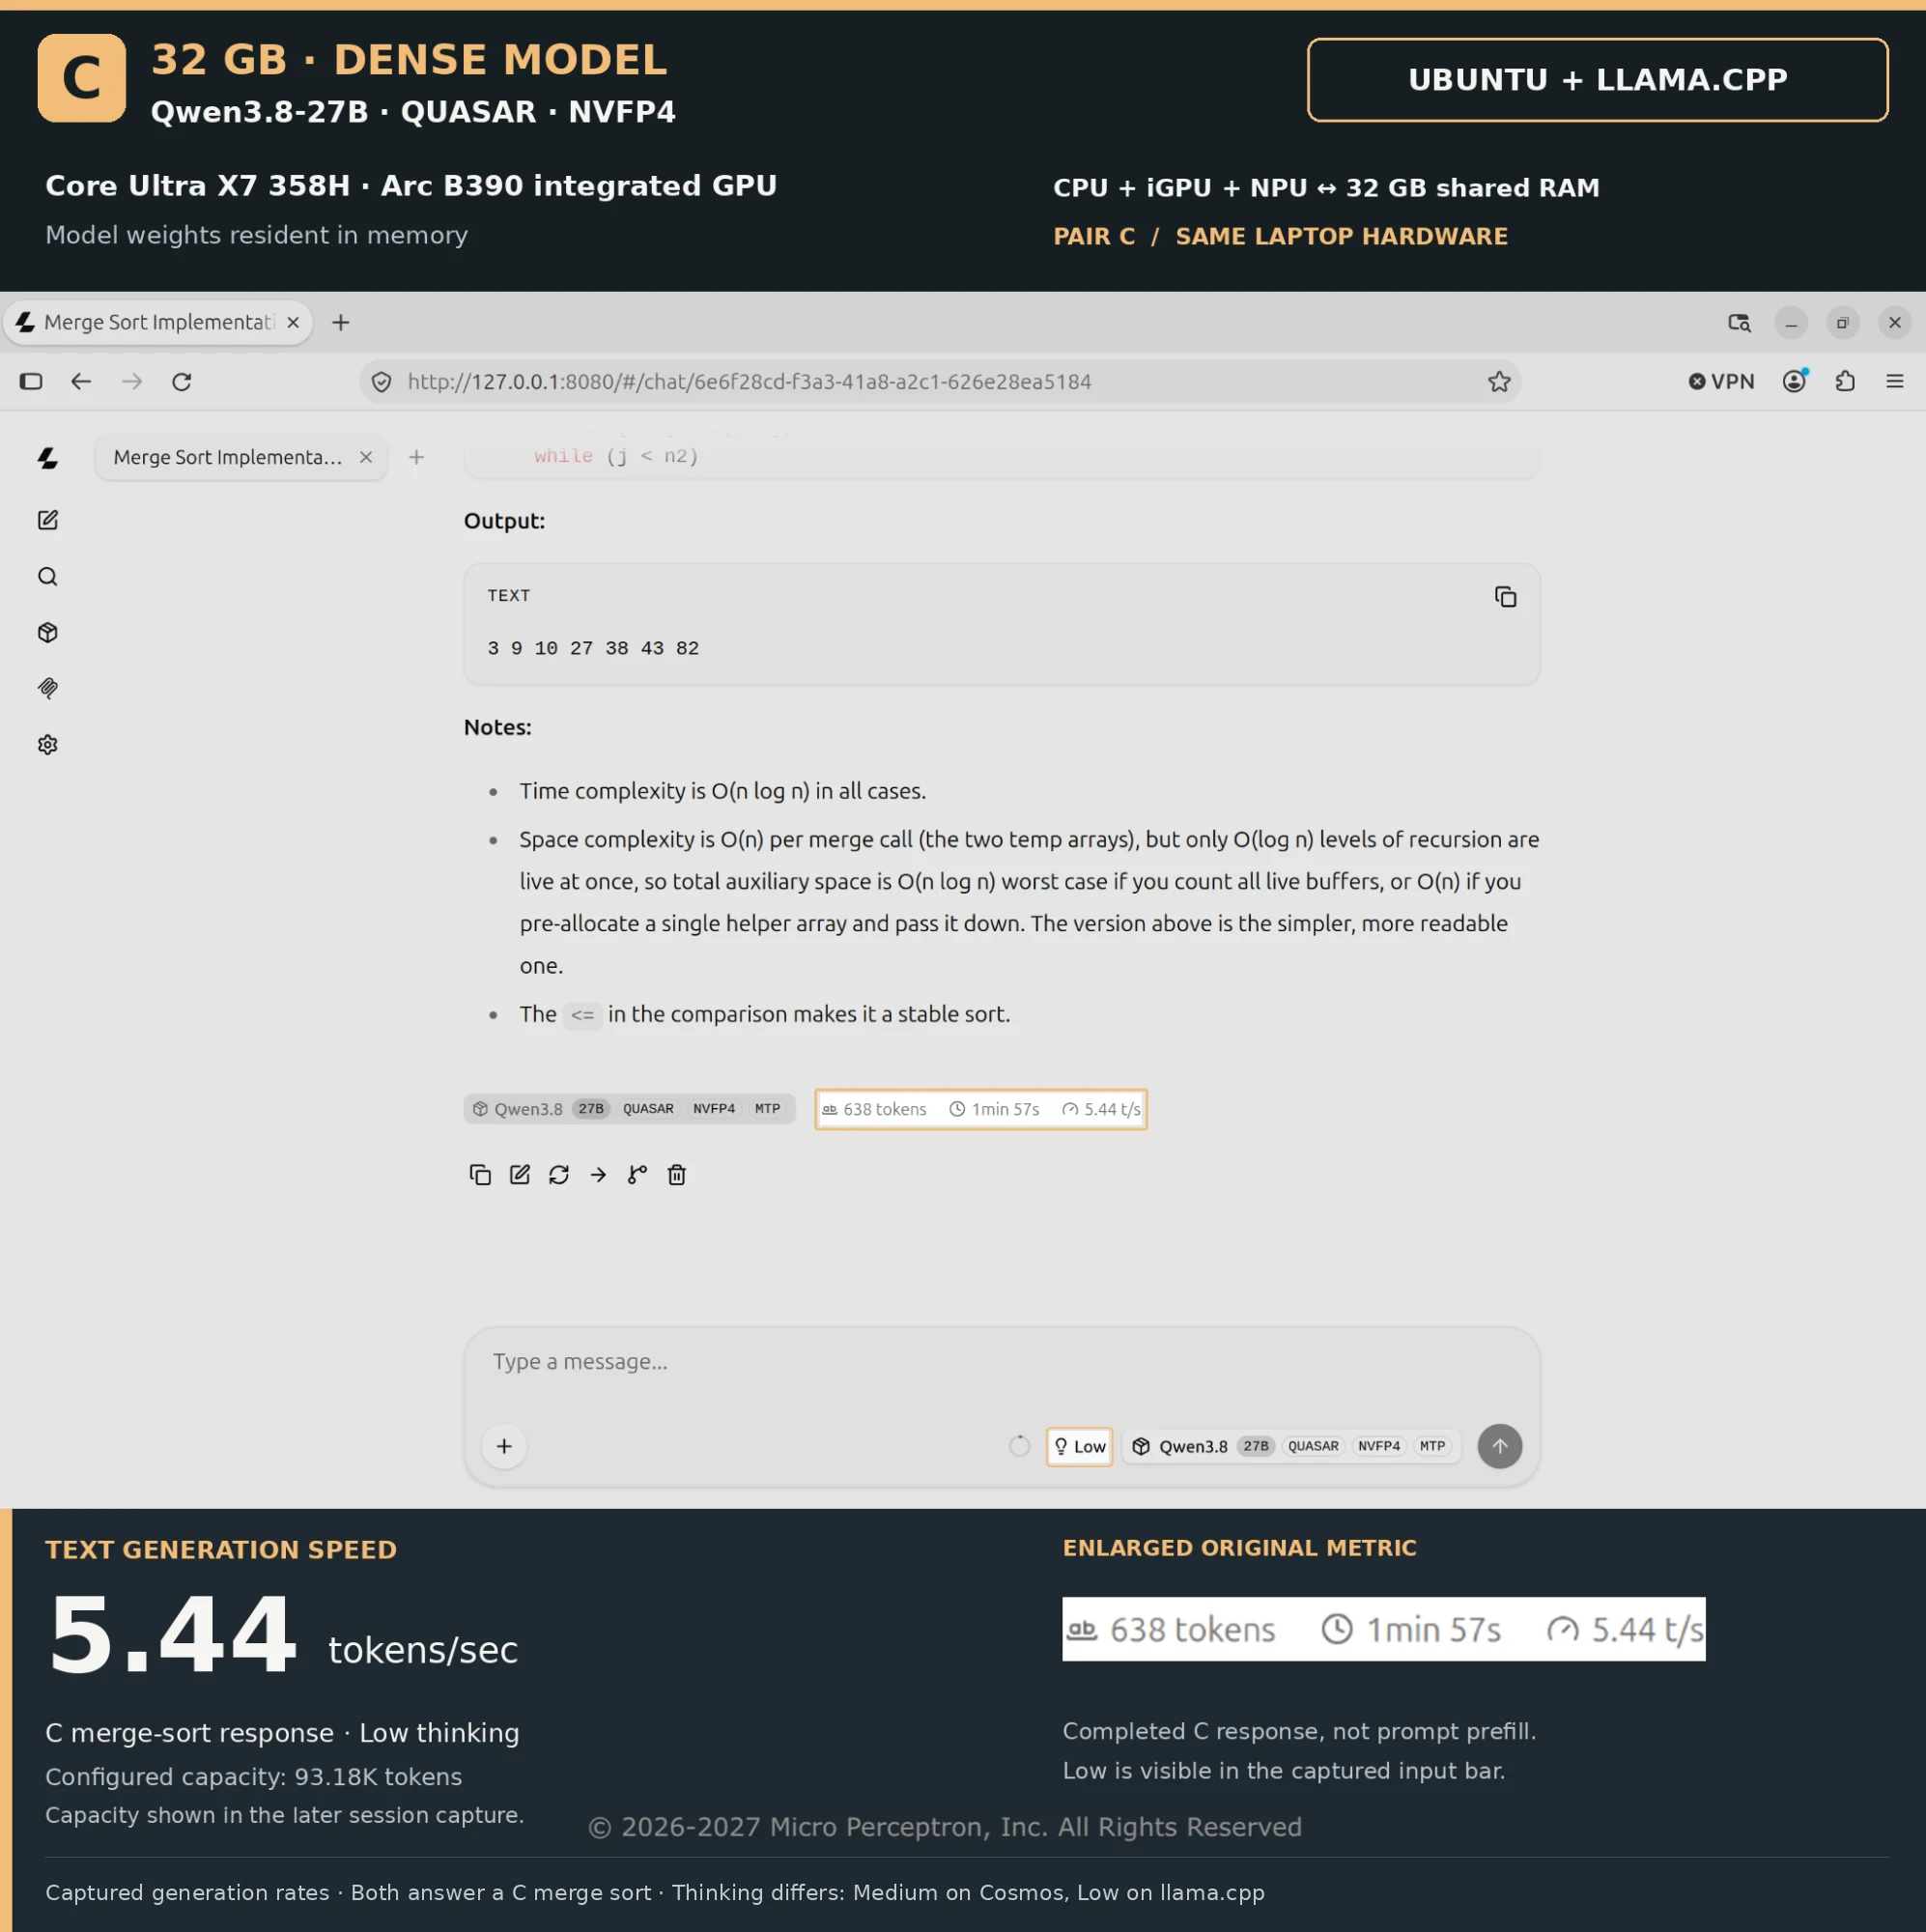
A 27B dense model on the same 32 GB laptop, every weight resident in memory on both systems. Both captures answer a merge sort in C; on Cosmos it's the first answer in a fresh chat. Thinking was set to medium on Cosmos and low on llama.cpp.
- Laptop
- MSI Prestige 16 AI+ C3MTG
- CPU
- Intel Core Ultra X7 358H
- GPU
- Intel Arc B390 · Xe3 (integrated)
- Memory
- 32 GB, shared by CPU, GPU and NPU
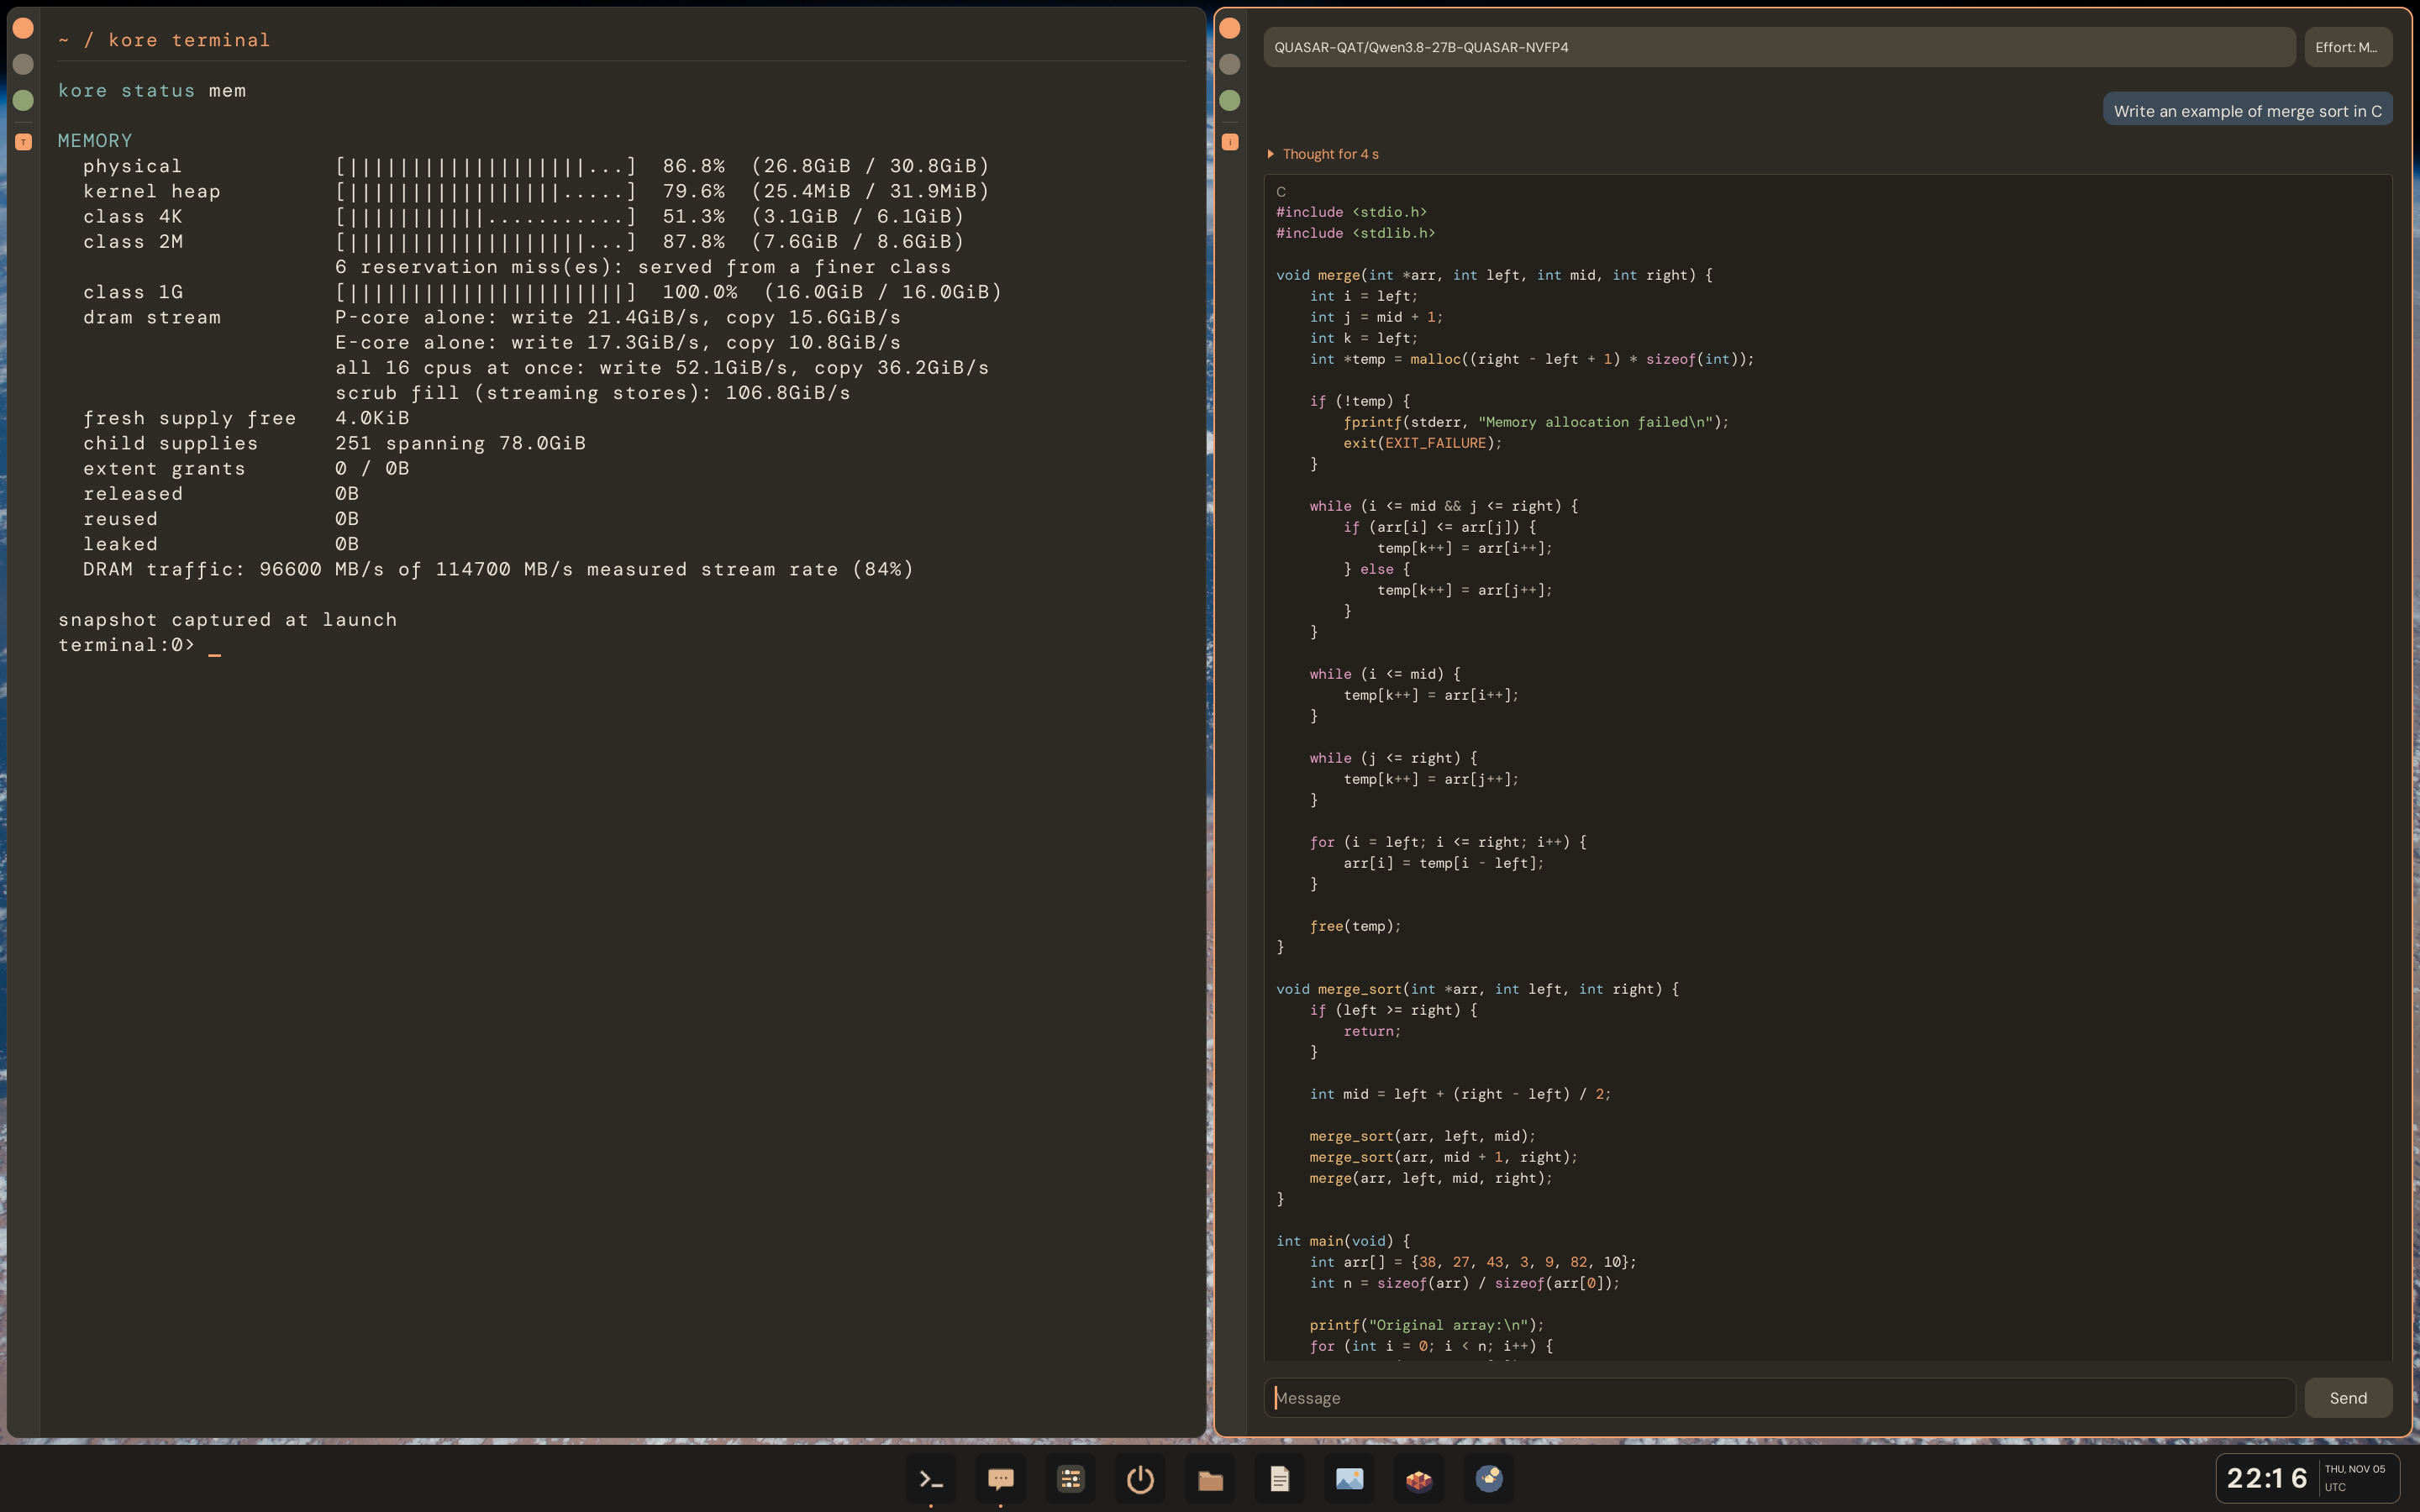 (open full size)
The same Cosmos chat as the answer began: the prompt is its first message.
Decode speed on this laptop · 4.4× the speed of Ubuntu + llama.cpp on the same machine
- Cosmos
- 24.0tok/s
- Ubuntu + llama.cpp
- 5.44tok/s
Readouts, as shown on screen
586 tokens at 24.0 tok/s · context 2124 of 180224 · 5.38 tokens a step
Context 2,124 / 180,224 · 5.38 tokens per decode step · Medium thinking
638 tokens · 1min 57s · 5.44 t/s
638 tokens in 1 min 57 s · Low thinking
The thinking setting sets how long the model thinks before it answers; each figure is the decode rate of the answer itself. llama.cpp's is the fastest answer captured in its session, and its average across all turns read 3.7 t/s.
What each system ran
- Weights
- BothQwen3.8-27B · QUASAR · MTP · NVFP4
- System
- CosmosCosmos on Kore
- Ubuntu + llama.cppUbuntu, on the same laptop · version not recorded
- Runtime
- CosmosKore's inference engine · built-in chat
- Ubuntu + llama.cppllama.cpp, an earlier build · version not recorded · web UI
Evidence
 (open full size)
 (open full size)
How it was measured
- Same machine
- Every comparison ran on one laptop, with the same silicon, drive and model weights on each side. On metal, Cosmos and Ubuntu were booted in turn; a result that ran Cosmos as a guest says how the guest was set up.
- Current baseline
- Ubuntu 26.04.1 LTS on Linux 7.0.0-38 with the latest Intel Xe drivers, on both machines; llama.cpp 0.8, with native NVFP4 and expert-cache support; fio 3.41 with io_uring, direct I/O and registered buffers, as the storage result's commands show. Current releases, not old builds, with one exception: the 27B result's llama.cpp run used an earlier build whose version wasn't recorded, and its settings say so.
- Captured runs
- Each figure is one captured run, read off its screenshot — not an average of repeated runs.
- Native harnesses
- Each system is measured with its own tools: Cosmos's chat and pack bench; llama.cpp's web UI and fio on Ubuntu. Transfer sizes and scheduling are reported, not equalized.
- Units
- Storage in decimal GB/s (10⁹ bytes per second). Tokens per second as each runtime reports its own generation speed.
- Setup excluded
- Buffer allocation and registration happen before timing on both systems; Cosmos prints its setup time on a separate line.
More results
- Local inference32 GB RAM laptop: every weight resident in memory42.5 tok/s · 32 GB
- Local inference16 GB RAM laptop: a model larger than its memory, streamed from SSD13.2 tok/s · 16 GB
- As a guest32 GB RAM laptop: Cosmos as a guest of Ubuntu, on one virtual function of the GPU37.9 tok/s · 32 GB
- StorageNVMe raw read6.02 GB/s · 16 GB